Self-Hosted LLM
Insights on Self-Hosted LLM.
Local LLM Hardware Requirements: GPU, VRAM and RAM Sizing
Local LLM hardware requirements explained: the GPU, VRAM, RAM and storage you need to run 7B to 70B AI models on your…
Read →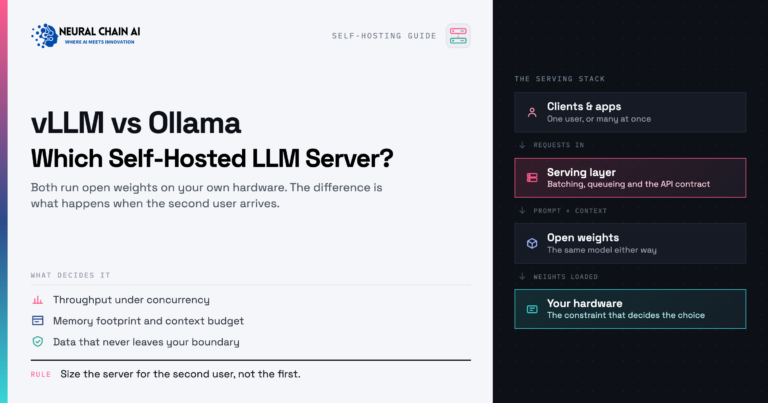 Local LLM
vLLM vs Ollama: Which Self-Hosted LLM Server Should You Run?
vLLM vs Ollama compared on throughput, concurrency, GPU cost, and setup. See which self-hosted LLM server fits your workload and when to…
Read → Local LLMHow to Run an LLM Locally: A 2026 Business Guide
How to run an LLM locally for your business in 2026: a practical guide to the tools, open models, hardware and setup…
Read → Local LLMvLLM vs SGLang vs TensorRT-LLM: Production Inference Engine Guide
vLLM vs SGLang vs TensorRT-LLM: a 2026 guide to choosing the right production LLM inference engine, compared on throughput, latency, features and…
Read → Local LLM
Best Local LLM for Business in 2026: Top Open Models Ranked
The best local LLM for business in 2026: top open models ranked by quality, speed and hardware needs — including the best…
Read → Local LLM
Is a Local LLM Worth It for Business? A Cost Breakdown
Is a local LLM worth it for business? A clear cost breakdown of self-hosted AI vs cloud API pricing — GPU and…
Read →