Insights
LLM Inference
Insights on LLM Inference.
Local LLM 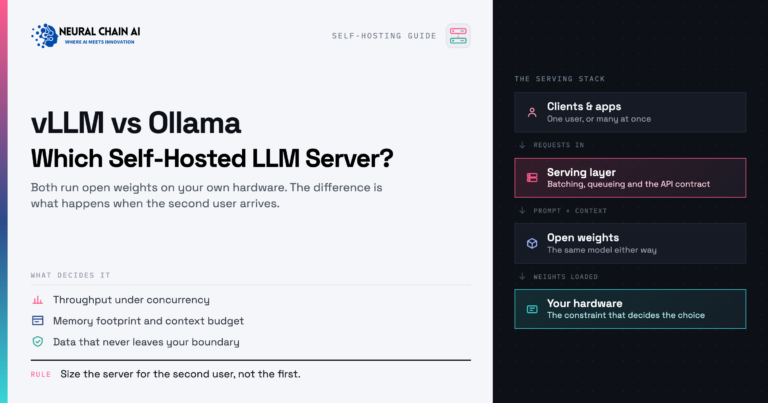 Local LLM
 Hardware Requirements: GPU, VRAM and RAM Sizing
Local LLM hardware requirements explained: the GPU, VRAM, RAM and storage you need to run 7B to 70B AI models on your…
Read →
Local LLM vLLM vs Ollama: Which Self-Hosted LLM Server Should You Run?
vLLM vs Ollama compared on throughput, concurrency, GPU cost, and setup. See which self-hosted LLM server fits your workload and when to…
Read → Local LLMvLLM vs SGLang vs TensorRT-LLM: Production Inference Engine Guide
vLLM vs SGLang vs TensorRT-LLM: a 2026 guide to choosing the right production LLM inference engine, compared on throughput, latency, features and…
Read →